Say you log ten days in a row. Entries, exits, screenshots, a note about how the session felt. Then a Wednesday arrives where you take three trades, break two rules and lose 2.4R. You close the laptop. The next day you log the winner and skip the loss. By week three the only rows left in the file are the ones that make you look competent.
That file is now worse than no journal at all, because it looks like evidence. The 2010 study in The Review of Financial Studies tracked complete brokerage records for individual investors in Finland from 1995 to 2003 and found that performance improved and the disposition effect weakened with experience, but that part of the apparent improvement came from weaker traders quitting the market. The authors concluded that ignoring the people who leave substantially overstates how quickly investors learn (investor learning and attrition in The Review of Financial Studies).
Your journal has the same bias, one trader wide. When losses drop out of the record, the averages flatter you and every improvement you "find" is an artifact of what you chose to write down.
Three jobs keep it honest. Measure the process (setup, size, rule adherence). Capture market state (funding, liquidations, session, open interest). Prove repetition across a sample big enough that one good week can't carry it. If a journal does only the first, it's a diary. If it does none, it's a spreadsheet you'll abandon by Friday.
Here's the minimum standard worth adopting, because it fits inside a bad week: a trade counts as logged only when entry, exit, size and the reason you took it are saved the same day. Everything else is an upgrade you can add later. The habit mechanics behind that standard are the same ones in this guide to how to start a journal: fix a time, keep the entry short, and let the record accumulate before you pass judgment on it. Pair it with a repeatable crypto trading daily routine and the logging stops depending on mood.
Ten fields cover everything that changes the result of a perp trade. Add more if you like, but don't drop below these, because a review can't answer questions the original record never asked.
| Field |
What to record |
Example |
| Timestamp (UTC) |
Entry and exit time in UTC, never local time |
07:50 UTC entry, 10 minutes before an 08:00 UTC funding event |
| Margin mode and position multiple |
Isolated or cross, plus the multiple actually used on the position |
Isolated, 10x on $1,000 margin, so $10,000 notional |
| Liquidation price |
Exchange-reported liquidation price and distance from entry |
$64,000 long with liquidation at $61,300, 4.2% below entry |
| Risk in dollars and R |
Dollars at risk to the stop, and the same figure in R |
$150 to the stop, so 1R is $150 and a 2R target is $300 |
| Setup |
One name from a fixed list |
Breakout retest, funding fade, liquidation sweep |
| Entry reason |
One sentence written before the order |
Breakout level retest holds, stop placed below the retest |
| Emotion at entry |
One tag from a fixed list plus intensity from 1 to 5 |
Confident 3, FOMO 4 |
| Funding at entry |
Rate and interval, with sign showing whether you pay or receive |
+0.05% per 8 hours, long pays, three payments a day |
| Exit reason |
One value from a fixed list |
Stop hit, invalidation (closed below level), target reached |
| Context snapshot |
Open interest change, dominant liquidation side, volume |
Open interest up 3% over 4 hours, short liquidations dominant |
Time zone is the first. Binance funding lands at 00:00, 08:00 and 16:00 UTC, while other venues run different schedules, so a 07:50 UTC entry sits ten minutes before a funding event and an otherwise identical 08:10 entry has just cleared one. Same chart, different cost basis. Record the UTC time, the venue, the session label and the minutes until the next funding event as numbers so they can be filtered later. When you review, funding you collected is a fact about the venue's clock, and only a timestamped entry keeps it from being credited to the setup.
Definitions are the second. Write your setup list, session list, emotion list and exit-reason list before the first trade of the sample, and don't edit them once results exist. A "breakout retest" that meant a 1% pullback in week one and a 3% pullback in week three is two setups sharing a name, and the averages merge them. A setup name that shifts meaning halfway through a month voids the comparison; adding a new name and starting a fresh count doesn't.
A few fields only exist at exit: the worst adverse move, total funding paid or received, final R. That's expected. What can't happen is deciding after the fact which bucket a trade belonged to. Hold the fields and the lists fixed, and the record stays comparable long enough for a weekly review to mean anything.
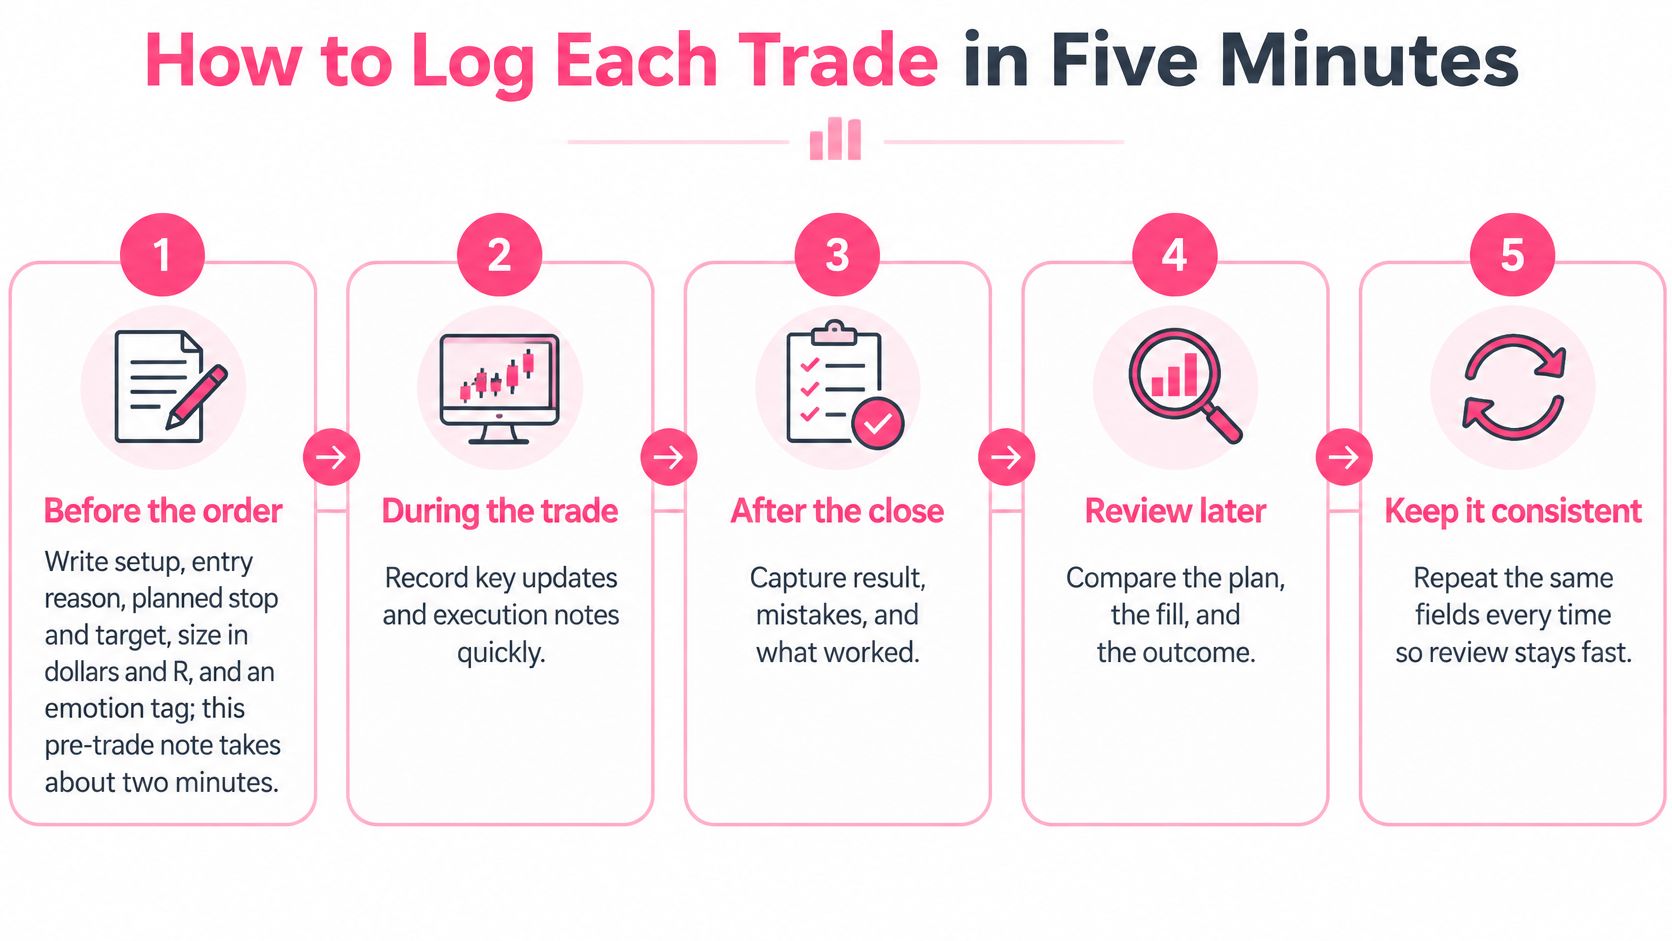
A routine that takes twenty minutes per trade lasts about six days. This one takes five, spread across the life of the position instead of dumped into one end-of-day session.
-
Before the order, roughly two minutes of writing. Setup name, the entry reason in one sentence, planned stop and target, size in dollars, risk in R, and one emotion tag with intensity. This is the only part you can't rebuild later. Once the trade closes, memory rewrites the reason to match the outcome, and a fabricated rationale is worse than a blank cell. If you can't write the sentence, you don't have a trade.
-
At the fill, thirty seconds. Fill price, UTC timestamp, margin used, and a snapshot of open interest change, liquidation volume by side, spot versus perp price, and traded volume. Most of this sits on the data panel next to the order ticket, so it's a copy job, not research.
-
During the hold, one line each time it matters. Add a timed note whenever price moves 1R against you or comes within 2% of your liquidation price. Two or three notes per trade is normal, and they explain later why you cut early or sat through it.
-
At exit, another thirty seconds. Exit price, fees, funding paid or received during the hold, final R, and an exit reason from the fixed list. Use net figures. A gross +1.5% that paid funding all week is a different trade than the chart shows.
-
Once a week, reconcile against exchange history. Missing fills, duplicate imports, and the position you swear you closed all surface here and nowhere else. Ten minutes of matching totals catches errors that would otherwise contaminate a month of review. If a row won't reconcile, flag it and leave it in rather than guessing a number.
The order of these steps is the point. Steps one and two are cheap because they happen before you know how the trade ends.
One screenshot per trade, with entry and exit marked, replaces a paragraph of description. Attach it and move on.
Practical rule: if a trade goes unlogged, log it late with a "late entry" flag instead of deleting it. A flagged row still counts in the sample. A deleted row silently improves your record.
Manual entry works as long as every field gets filled. If you'd rather the tool hold the trade record and the market context in the same row, Thrive Pro runs this loop with less retyping: trades can be logged by hand or synced from exchange accounts over read-only API credentials, with trade history refreshing every 15 minutes, and entries carry emotion and psychology tags alongside a performance dashboard with equity curve and R-multiples. It costs $99/mo after a 7-day free trial. Chart screenshots attach to entries. If your venue isn't supported for automatic sync, importing your trades from a CSV file brings up to 12 months of history into the journal without retyping a single fill.
A perpetual has no expiry, so the exchange keeps its price near spot with a recurring transfer between longs and shorts. Record that transfer on every trade, because a winner on the chart can be a loser on the statement.
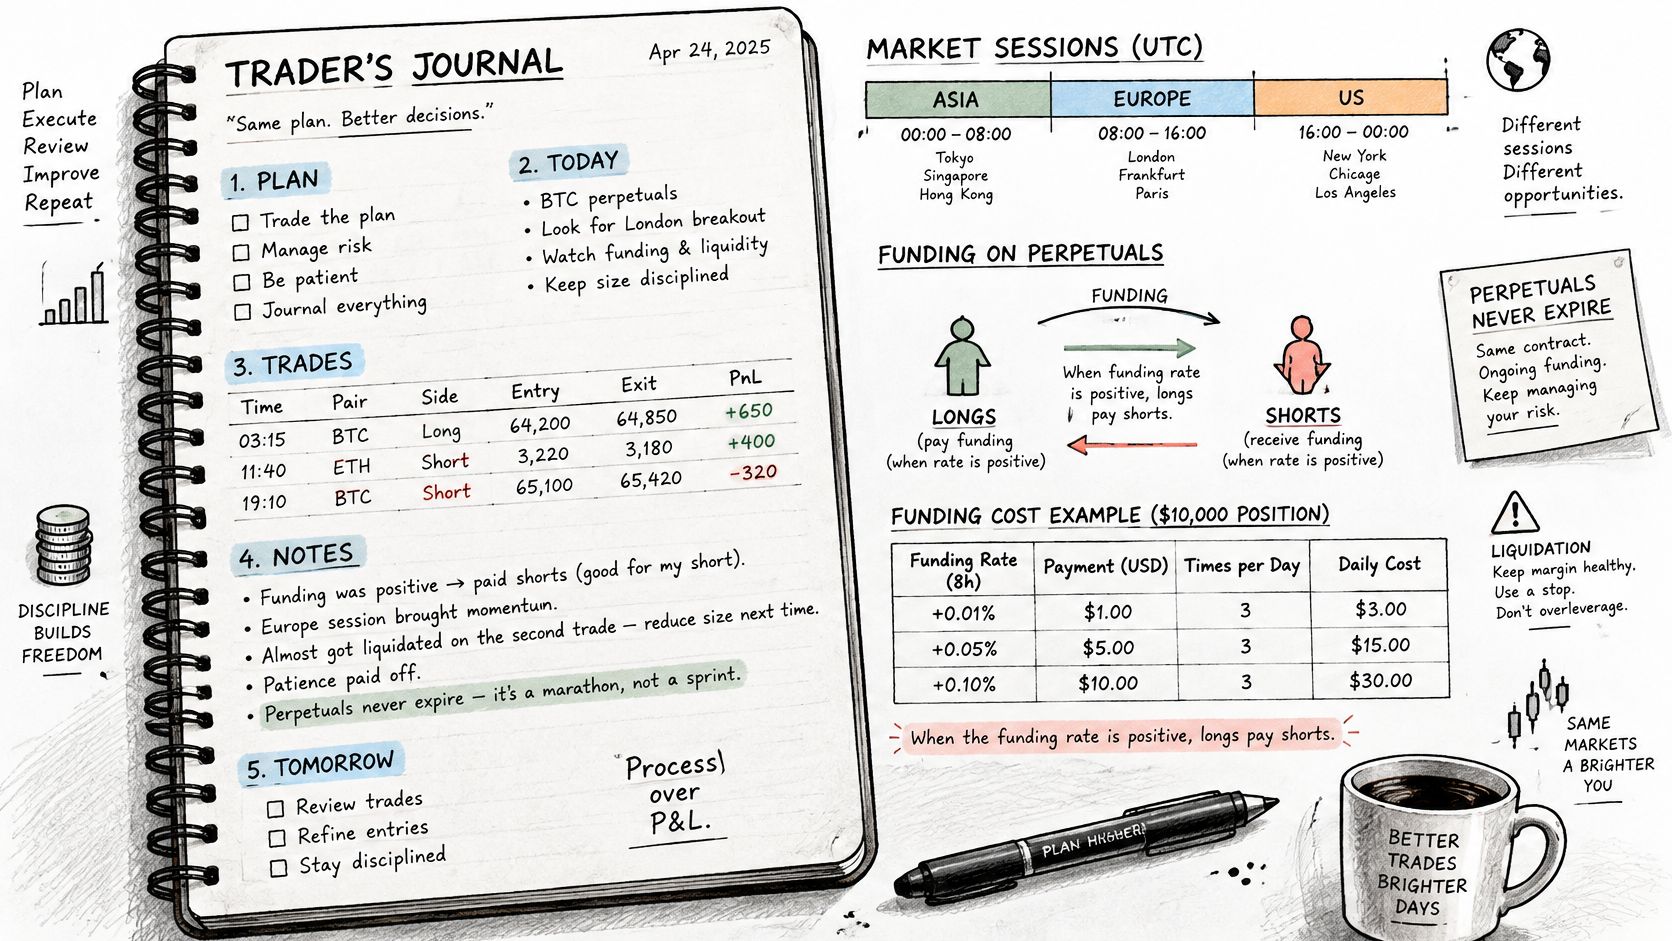
When the perp trades above spot, funding is generally positive and longs pay shorts; below spot it's negative and shorts pay longs. A common schedule is every eight hours, though the interval depends on the venue, and a $10,000 long held through a 0.01% payment pays $1 for that interval before fees or price movement (perpetual funding mechanics in a study of crypto derivatives). Scale that up and the drag gets real.
| Funding rate per interval |
Cost per payment |
Daily cost (3 payments) |
Weekly cost (21 payments) |
| 0.01% |
$1.00 |
$3.00 |
$21.00 |
| 0.05% |
$5.00 |
$15.00 |
$105.00 |
| 0.10% |
$10.00 |
$30.00 |
$210.00 |
Work one example through. A $10,000 long held a week at 0.05% pays $105 in funding before any fees. If the trade gains 1.5% gross, that's $150, so it nets about $45, or 0.45% of notional. On a spreadsheet that says +1.5%, that trade looks like a decent week. In the journal it's a marginal one, and knowing the difference changes how long you're willing to sit in a crowded long.
Market context decides whether a trade was a good decision or a lucky one. A long entered as open interest rises while short liquidations dominate is a different environment from a long entered immediately after a sharp long-liquidation cascade, even when the entry candle looks identical on both.
So record three snapshots per trade: at entry, at exit, and at the highest-stress point during the hold. Open interest direction, liquidation volume by side, and whether the position was isolated or cross-margin. Later, compare the same setup across low-crowding, expanding-open-interest conditions and crowded, deleveraging ones. If you want the full field list and how to read each one, this playbook on funding rates and open interest in crypto trading covers the same ground.
That comparison is where the honest conclusions live. A losing trade executed inside a forced deleveraging cascade can reflect sound process. A winning trade built on one-sided positioning can be luck wearing a good entry. Without the context fields you can't tell them apart, and you'll bank the wrong lesson.
The session logic ties it together. A trade is only comparable to another if its UTC session and minutes-to-next-funding were recorded the same way. A loss logged as "evening trade" tells you nothing. A loss logged as 23:55 UTC entry, five minutes before funding, in an Asia session with open interest falling, tells you something you can act on.
Free-text emotion notes feel productive and test nothing. One study followed 69 day traders who filed daily emotional and performance questionnaires, producing 755 usable daily reports across five weeks, and found that traders with stronger emotional reactions to both gains and losses performed significantly worse (study of day traders' emotions and performance). Experiments in simulated markets point the same direction: participants scoring higher on overconfidence tended to perform worse.
Fixed tags beat paragraphs. Use five to seven states: calm, confident, fearful, FOMO, frustrated, revenge, bored. Write a one-line definition for each before you tag the first trade, because a state that changes meaning between weeks can't be tested against itself. Score intensity 1 to 5 at entry, then score again after any loss. A paragraph about how you felt can't be sorted. A "FOMO 4" can.
Tools built for journaling already treat this as a structured field. Thrive Pro, for instance, carries emotion and psychology tags on each trade, so the state sits in the same row as the entry, exit and R result instead of floating in a note.
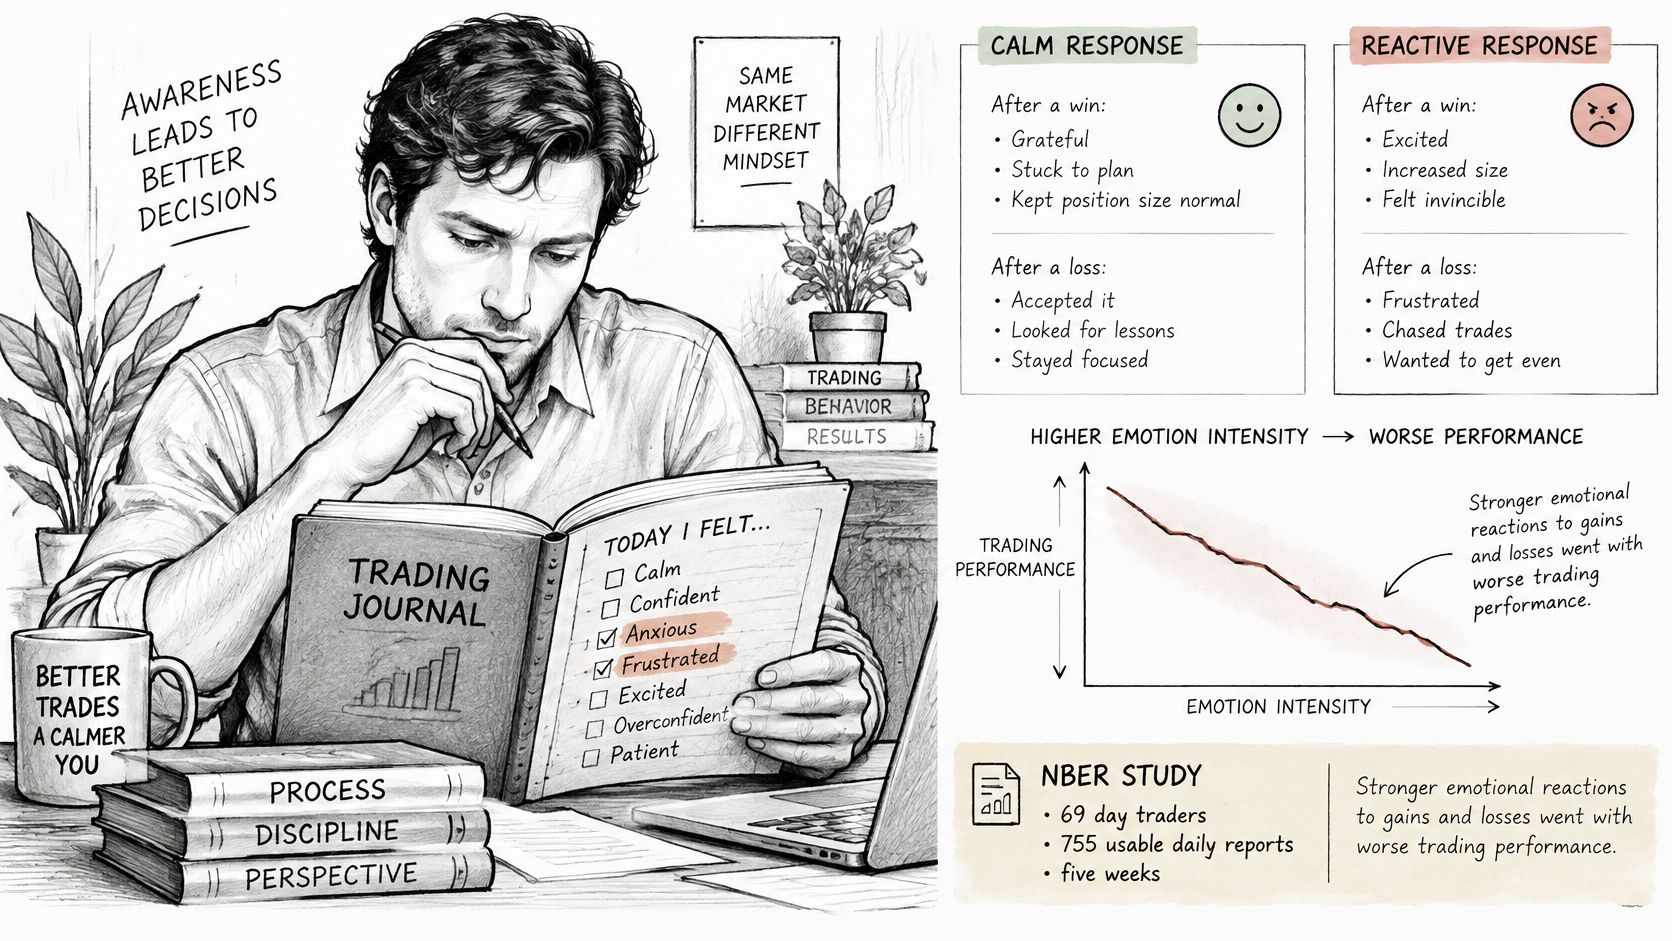
Run the first comparison after roughly 30 trades. Pull average R, average loss size, rule breaks, holding time and results split by tag. Twelve FOMO-tagged trades averaging -0.4R against eighteen calm trades at +0.6R doesn't prove FOMO causes losses. It does justify a written rule, such as requiring a second confirmation on any entry you'd tag FOMO, then measuring whether the rule moves the average over the next sample.
If a tag barely appears, fold it into the nearest state instead of reading a pattern into noise. Seven tags where three get used is worse than four that all carry real volume.
An emotional trade isn't automatically a bad trade. The point is finding patterns that cost R and deciding whether a rule reduces them.
Keep the tag counts in the same template as your other splits, so every comparison pulls from the same rows. Turning reflection into actionable decisions is the same loop applied to money. When the tag analysis keeps surfacing the same bias, a trade journal can detect behavioral bias across a real sample rather than a hunch.
The rule that saves the review: freeze the categories before you look. Sessions, setups, emotion tags and exit reasons are defined before the week's results exist and stay unchanged for the whole sample. Then run the same six steps every week.
- Confirm the frozen definitions. If you edited a setup name mid-week, that trade drops out of the comparison rather than being reclassified.
- Calculate net profit after fees and funding paid, plus funding received.
- Run the five core metrics: win rate, profit factor, average R, maximum drawdown and drawdown duration.
- Split the same trades by setup, direction, asset, session, funding condition and emotion tag.
- Write down what you saw without touching the rules during the week. Observations go in the notes, not into the strategy.
- Carry a pattern forward only if it repeats across several weeks of the same classification.
| Metric |
How to calculate |
What it tells you |
| Net profit after fees and funding |
Realized P&L minus trading fees minus funding paid, plus funding received |
The true weekly result, not the gross price move |
| Win rate |
Winning trades divided by closed trades |
How often the setup pays, but meaningless without average R |
| Profit factor |
Gross profit divided by gross loss |
Above 1.0 means winners outweigh losers in total |
| Average R |
Sum of R results divided by number of trades |
Result per unit of planned risk, comparable across position sizes |
| Maximum drawdown |
Largest fall from an equity peak to the following trough |
The worst stretch you actually sat through |
| Drawdown duration |
Days from an equity peak until equity recovers |
Whether losing periods are short or drag on for weeks |
Five New York-session trades total 3.0R. Three Asia-session trades total 1.0R. Record the difference, note it, and repeat the classification next week. Do not rewrite the strategy around eight trades, and don't start skipping Asia entries because of one sample. Performance research typically evaluates return, profit factor, maximum drawdown and drawdown duration, while work on overfitting stresses parameter stability across different lookback periods, which is the professional version of the same warning (study of performance evaluation and drawdown measures).
One week of perpetual trades almost never supports a conclusion. What a good weekly review produces is a short list of things to keep watching, not a new rulebook. If you want a baseline to measure weeks against, building a performance measurement baseline keeps the comparison stable while the sample fills in.
Set up the ten day-one fields now, before the next position. Freeze your session list and setup list in the same sitting, and write the definitions down so a borderline trade gets classified the same way in week six as it does today. Then log the next five trades with the five-minute routine and review nothing until all five are in the file.
A journal that survives a losing week is worth more than a perfect template abandoned after one bad trade. If your exchange is already connected through read-only API credentials, the first sync imports up to 12 months of trade history, which is enough for a real baseline instead of a feeling. If you would rather have the record read for you than interpret it yourself, the Weekly AI Coach on Pro+ works from your own closed trades and needs at least three per week.
Thrive puts the trade record, the funding and liquidation context, and the emotion tags in the same row, so a weekly review is a filter change instead of an hour of copy and paste. Log five trades, run one review, and see whether the pattern you have been guessing at shows up in your own data.